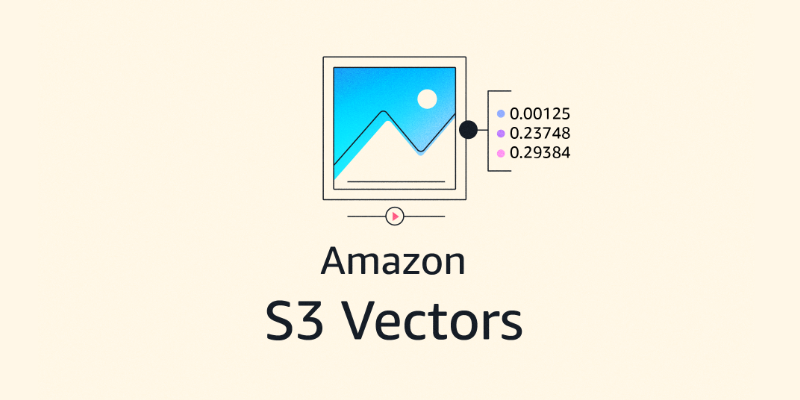
DjangoCon Europe 2027 is heading to Innsbruck, Austria! 🏔️⛷️🚠🇦🇹
Posted by DjangoCon Europe 2027 Organizing Team on Sept. 15, 2026
1 min readNews
Posted by DjangoCon Europe 2027 Organizing Team on Sept. 15, 2026
Posted by Jeff Triplett and the DSF Board on Sept. 16, 2026
The August 2026 security release for Next.js is now available
Turbopack’s chunking speeds up page loads and enables sharing code across pages. We shipped new experimental features to improve chunking in Next.js 16.3.
How the Next.js team used an agent to research old reports and work through the issue backlog.
I'm excited to announce that native histogram support for Kubernetes metrics is graduating to Beta and is enabled by default in Kubernetes v1.37! Native histograms (previously introduced as Alpha in Kubernetes v1.36 under KEP-5808) bring high-resolution, low-cardinality observability to Kubernetes metrics. By adopting Prometheus Native Histograms, Kubernetes components now expose latency and duration metrics with far greater accuracy while significantly reducing telemetry storage and scraping overhead. Why move beyond classic histograms?Since the early days of Kubernetes observability, duration and latency metrics (such as API server request latencies or scheduling durations) have relied on classic Prometheus histograms.
Memory QoS has graduated to Beta in Kubernetes v1.37 and is now enabled by default. On Linux nodes running cgroup v2, the feature uses the memory controller to give the kernel better guidance on how to treat container memory. It was first introduced as Alpha in v1.22, and expanded in v1.36 with tiered memory reservation. This post covers what changed in v1.37, what the Beta promotion means for cluster operators, and how to configure the feature.
Changed Block Tracking (CBT) support for CSI drivers shipped as Alpha in September 2025. With the March 2026 v1.0.0 release of the external-snapshot-metadata project, the feature moved to Beta. If you aren't yet familiar with changed block tracking for storage in Kubernetes, the Alpha announcement covers the motivation, the three primary components (the CSI SnapshotMetadata gRPC service, the SnapshotMetadataService CRD, and the external-snapshot-metadata sidecar), and a walkthrough of how to use the API. CBT currently applies to block volumes; file-volume and network file-share changed-list tracking is not covered by this feature. This post focuses on what is different in Beta.
Today, we’re excited to introduce the newest members of the AWS Heroes program. AWS Heroes are a vibrant, worldwide group of AWS experts who go above and beyond to share knowledge, mentor others, and build thriving communities. These individuals make a real difference in helping developers and organizations succeed with AWS. This month, we welcome […]
Amazon Aurora PostgreSQL now lets you directly query Apache Iceberg and Parquet data stored in your data lake alongside live operational data—no ETL pipelines required. Powered by DuckDB embedded within Aurora, this capability enables single queries that join transactional and historical data using familiar PostgreSQL syntax. It supports AWS Glue Data Catalog, S3, and S3 Tables, with optimizations like predicate pushdown and caching for efficient performance.
YOLO mode lets an AI agent run without asking permission. Learn what it is, why it's risky, and how to run it safely.
Amazon S3 Vectors now supports metadata pre filtering, delivering up to 5x higher recall on filtered searches. Filters evaluate before similarity search so scoped queries return more relevant results. Ideal for RAG, agentic apps, and document search.